Decision Traces Aren't a B2B Problem. They're an Industrial Survival Problem
Ashu Garg argues in his recent piece that Google’s 20-year edge came from capturing decision traces at scale. Consumer software recorded every click, preference, and hesitation. Enterprise software never managed this because decisions are distributed across meetings, emails, and Slack threads. I agree with that observation entirely. But enterprise B2B misses something fundamental about where this problem gets truly acute: the industrial operationsfloor at 2 AM when a decision happens in the head of an operator who retires next year.
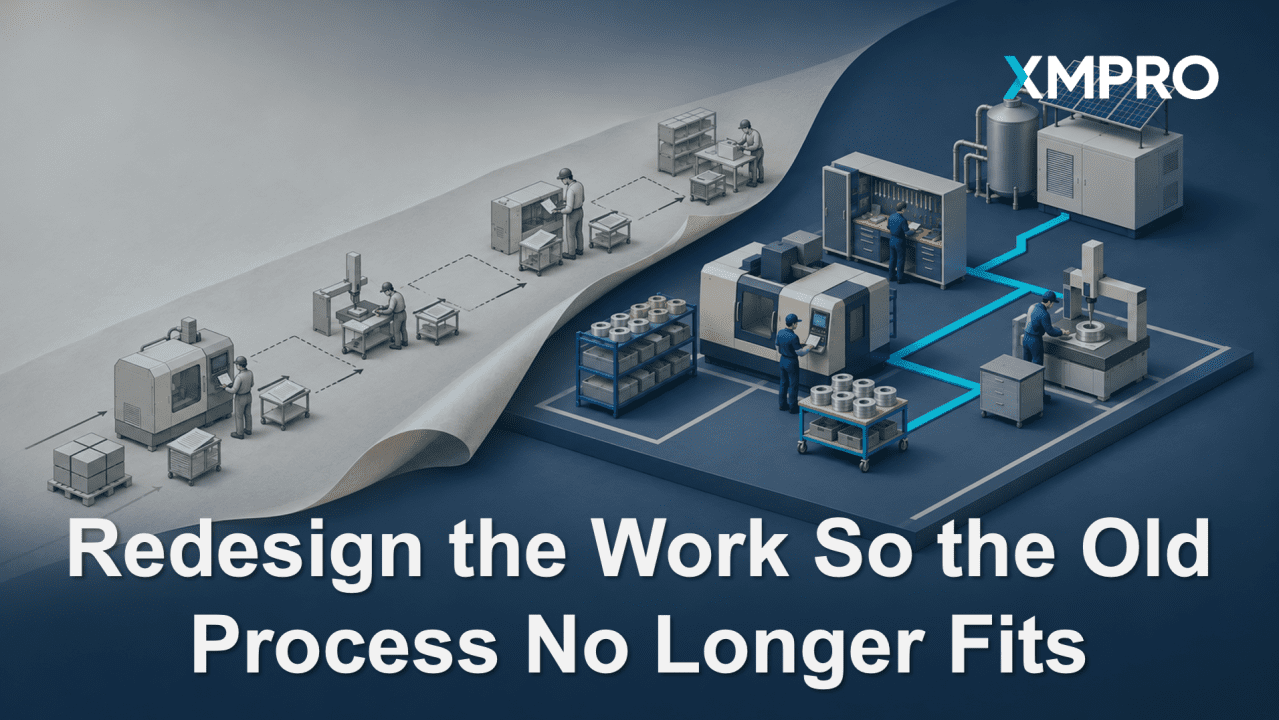
This isn’t about better dashboards or smarter search. It’s about the difference between two completely different write paths to knowledge, and why industrial operations can’t afford to keep pretending they’re the same as B2B.
The Write-Path Problem Nobody Talks About
Most discussions about decision traces focus on the read path. You query back through decisions to explain what happened or to improve the next decision. That’s valuable. That’s what Ashu describes.
**The write path is harder.**Recording a B2B decision means capturing what happened in email chains and calendar invites and Slack conversations. You can bolt this onto your software platform. You can log it. You can search it later. It’s awkward, but it’s possible.
Recording an industrial operations decision is different. The decision doesn’t happen in your software at all. It happens because a maintenance technician walks up to a pump and sees vibration numbers on an analog gauge that don’t match what was normal three months ago. It happens because a plant supervisor gets a call about a production delay and mentally connects it to the weather forecast, the maintenance schedule, and a policy about energy costs that nobody wrote down. It happens at 2 AM when nobody is documenting anything.
The decision gets made. Equipment runs or doesn’t run. Product ships or sits in storage. The shift changes. The person who made the decision goes home. Nobody recorded the reasoning.
Why Industrial Decisions Need Their Own Framework
B2B decisions are consequential, but they’re also documentable. They move through systems that have audit trails. A customer buys or doesn’t buy. A contract gets signed or rejected. Someone approved a budget or didn’t. There’s a digital artifact.
Industrial operations decisions are consequential and opaque. A maintenance decision depends on vibration data from a sensor on the fourth floor, work order history from a system that ran on SQL Server in 2011, weather data from an external source, production schedule information from the planning system, and a safety policy that exists in someone’s head because it was never formally written. All of that information lives in separate places. None of it talks to the others.
Here’s what’s worse: the person who made the decision correctly (because they understood those connections intuitively) will retire in two years. Their replacement will not have that knowledge. The replacement will make different decisions. Equipment will fail more often. Production will cost more. Safety margins will narrow.
This isn’t a technology problem yet. It’s an institutional memory problem. But it becomes a technology problem the moment you decide to solve it.
Regulatory Audit Meets Standards-Based Ontology
If you want to capture industrial decisions so they survive employee turnover, you can’t just bolt on logging. You need something structured.
The first requirement is regulatory compliance. Industrial operations don’t live in a world of preference logs. They live in a world of auditable decisions. When a critical decision happens on the plant floor, someone needs to be able to answer: “Who made this? When? Why? What information did they have? What policy guided them?” That’s not nice-to-have. That’s required.
That means you need PROV-O compliance. Provenance ontology. The W3C standard that lets you formally capture who did what, when, using what tools, based on what source data. Industrial auditors understand this. Regulators understand this. It’s the language of accountability in engineering.
The second requirement is a standards-based ontology. You can’t use a proprietary schema because the knowledge needs to outlive the software. Equipment manufacturers in Oil & Gas speak ISO 14224. Work order systems speak different dialects. Sensor streams speak time-series standards. If you want a decision trace to connect information from all of these sources, you need a shared semantic layer.
This isn’t new language. It’s not proprietary. It’s the language that industrial engineering uses. The system needs to speak it natively, not treat it as an import problem.
Cross-System Provenance Is the Actual Constraint
The write-path problem in B2B is aggregation. You need to collect decision signals from multiple apps. You build connectors. You log API calls. It’s tedious, but it’s linear.
The write-path problem in industrial operations is integration. A maintenance decision depends on vibration readings, historical work orders, current production schedules, equipment age, weather forecasts, and policy. Those sources don’t share data schemas. They use different ontologies. Some are real-time sensors. Some are historical archives. Some are human judgment.
You need to capture not just the decision, but the provenance of each input to that decision. What version of the equipment history? What time window for vibration baseline? Which weather forecast was being used (yesterday’s or this morning’s)? Which policy version?
Without that level of detail, the decision trace is useless for the next operator. They’ll make the same decision and get different results because their inputs were different, but they won’t know why.
This is why cross-system provenance matters in industrial operations. It’s not about logging who clicked what. It’s about recording the exact state of knowledge that existed at the moment a consequential decision was made, across systems that don’t talk to each other.
The Compounding Loop That Builds Institutional Memory
Here’s where industrial operations get interesting.
Recommended by LinkedIn
In B2B, better decision capture creates better personalization. You remember what the customer wanted before. You show them similar things. You improve conversion.
In industrial operations, every decision becomes a structured precedent. The next operator sees that the previous shift made a decision to replace a bearing at a certain vibration threshold, based on equipment age and weather conditions. That becomes a data point. Feed that across a hundred decision traces, and patterns emerge. You can now recommend bearing replacement thresholds that are more accurate than the manufacturer’s generic guidelines.
Every human correction becomes a training signal. When an operator makes a different decision than the system suggested, that difference gets recorded. Why did they overrule it? Was the vibration threshold wrong? Did they know something about weather forecasts that the system missed? That becomes the next learning cycle.
The system gets smarter with use. That’s not unique to industrial operations. What’s unique is the compounding effect. In B2B, the loop is: better data on user preferences means better recommendations. In industrial operations, the loop is: better provenance of operating decisions means better asset management, lower failures, safer operations, and longer equipment life.
The value compounds in operational outcomes, not just in feature adoption.
The Institutional Memory That Walks Out the Door
This is the stakes. The companies that capture the reasoning behind operational decisions will own something that most competitors are losing every day: the institutional memory that retiring engineers are walking out the door.
An engineer with 30 years on the plant floor doesn’t just know the equipment. They know the correlations that matter when you’re making decisions under incomplete information. They know which maintenance decisions cascade into better production stability. They know the unwritten policies that exist in the gap between what the handbook says and what actually works.
That knowledge is not easily documented. It’s not in a notebook or a playbook. It lives in the pattern of decisions that person made across decades. It lives in the difference between their approach and their predecessor’s approach.
The organizations building decision trace infrastructure for industrial operations aren’t building a better dashboarding system. They’re capturing something closer to what Ashu described: the behavior patterns that drive value. In this case, the behavior is operational decision-making by people with deep domain knowledge. The value is operational resilience and institutional continuity.
What the Solution Actually Looks Like
We built this at XMPro. The XMPro Agentic Operations (AO) Platform captures decision traces as PROV-O compliant records stored in a semantic graph. Every time an agent team makes or recommends a decision, the system records the goal, the reasoning, the data sources consulted, the confidence level, the policies that applied, and the outcome.
The architecture has three layers that work together:
The first is an Operational Intelligence Model. This is a semantic knowledge graph that encodes institutional knowledge from multiple sources: sensor data, work order history, equipment specifications, safety policies, production schedules. It connects information that currently lives in separate systems and gives agent teams (and human operators) a shared operational context. Critically, human entries always outrank agent-generated knowledge. A safety engineer’s override is permanent and immutable. The system enforces an eight-level trust hierarchy so that institutional knowledge accumulates correctly over time. The second is the decision trace itself. When an agent team recommends bearing replacement based on vibration trends, the trace records which sensor readings were consulted, what time window was used for the baseline, which maintenance history informed the recommendation, and which policy governed the decision. If a human operator overrides that recommendation, the override and their reasoning become part of the record. The next operator, or the next agent team, sees both the recommendation and the correction. That’s the compounding loop. The third is governance. Agent teams operate under graduated autonomy levels. At lower levels, they observe and recommend. At higher levels, they act within defined boundaries. Every level has explicit constraints on what the agent is permitted to do before it does it. This is how you prevent the class of failure where an agent with correct permissions but no judgment causes damage. The system doesn’t just log what happened after the fact. It constrains what can happen before the fact.
The whole system produces regulatory-grade audit artifacts. When an auditor asks why a maintenance decision was made at 2 AM on a Tuesday, the answer isn’t “we don’t know.” The answer includes who (or what) made it, what information they had, what policy guided them, and what happened next.
This is in the XMPro AO Platform today. Not a roadmap item.
Where This Goes
The companies that do this systematically will have better asset utilization, faster root cause analysis, lower insurance costs, and (most importantly) the ability to scale expertise across facilities. The companies that don’t will watch their best people retire and wonder why their equipment starts failing more often.
That’s not a feature gap. That’s the future value of the enterprise.
Pieter van Schalkwyk is the CEO of XMPro, specializing in industrial AI agent orchestration and governance. Drawing on 30+ years of experience in industrial automation, he helps organizations implement practical AI solutions that deliver measurable business outcomes while ensuring responsible AI deployment at scale.
He authored the Industrial AI Agent Manifesto, published by the Digital Twin Consortium in February 2026, a governance framework for trustworthy autonomous operations
Our GitHub Repo has more technical information. You can also contact myself or Gavin Green for more information.
Read more on MAGS at The Digital Engineer
This article originally appeared on XMPro CEO’s LinkedIn blog, The Digital Engineer, on 7 April 2026.